Building and Automating Comprehensive LLM Evaluation Framework for SNAP Benefits
propel · Government · 2025 · source Agentic: no · promotional bias: low · source-backed · extracted with prompt 0.5.4 (schema v2)
Generated from extraction.json — do not edit by hand. Every claim cites verbatim source evidence; stated means the quote directly asserts the claim, implied means it supports it indirectly.
Problem
Domain: Public-benefits LLM evaluation
Propel needed a rigorous evaluation framework for SNAP-related questions that could benchmark base models for public value and guide an internal SNAP-specific assistant product.
Constraints:
- SNAP has many objective facts where wrong answers can harm clients.
- The product goal requires more opinionated criteria than a generic benchmark.
- Domain experts who are not software engineers need to participate in eval creation.
- Some criteria, such as accessible reading level, require model-judged evaluation.
Architecture
Propel built a SNAP eval framework using expert exploration, factual test cases, Promptfoo automation, Google Sheet-based eval authoring, multi-model comparison across GPT-4o-mini, Claude 3.5 Sonnet, and Gemini 2.0 Flash, and LLM-as-judge checks for more nuanced criteria such as reading level.
Diagram confidence: explicit (topology described by the source).
flowchart LR
  snap-expert[SNAP Expert] --> promptfoo-eval-suite[Promptfoo Eval Suite]
  google-sheet[Google Sheet] --> promptfoo-eval-suite[Promptfoo Eval Suite]
  promptfoo-eval-suite --> model-candidates[Model Candidates]
  promptfoo-eval-suite --> judge-model[Judge Model]
  promptfoo-eval-suite --> snap-assistant-product[SNAP Assistant Product]
Components
| Component | Role | Interacts with |
|---|---|---|
SNAP Expert |
Domain expert who probes model behavior and writes evaluation criteria. | Promptfoo Eval Suite |
Promptfoo Eval Suite |
Automated evaluation harness for SNAP questions. | Google Sheet, Model Candidates, Judge Model |
Google Sheet |
Accessible authoring surface for eval cases. | Promptfoo Eval Suite |
Model Candidates |
GPT-4o-mini, Claude 3.5 Sonnet, Gemini 2.0 Flash, and other models under test. | Promptfoo Eval Suite |
Judge Model |
LLM-as-judge evaluator for nuanced answer properties. | Promptfoo Eval Suite |
SNAP Assistant Product |
Future product informed by the eval framework. | Promptfoo Eval Suite |
Data flow
SNAP experts identify good and bad model outputs, encode factual questions and criteria into Promptfoo tests, run the same prompts across candidate models, check objective facts automatically, and use model-judge approaches for nuanced accessibility criteria.
Why this architecture
Propel separated benchmarking from product-specific evaluation because the public benchmark needs objective consensus while the assistant needs opinionated criteria. Promptfoo and Google Sheets made eval authoring accessible to SNAP experts rather than only engineers.
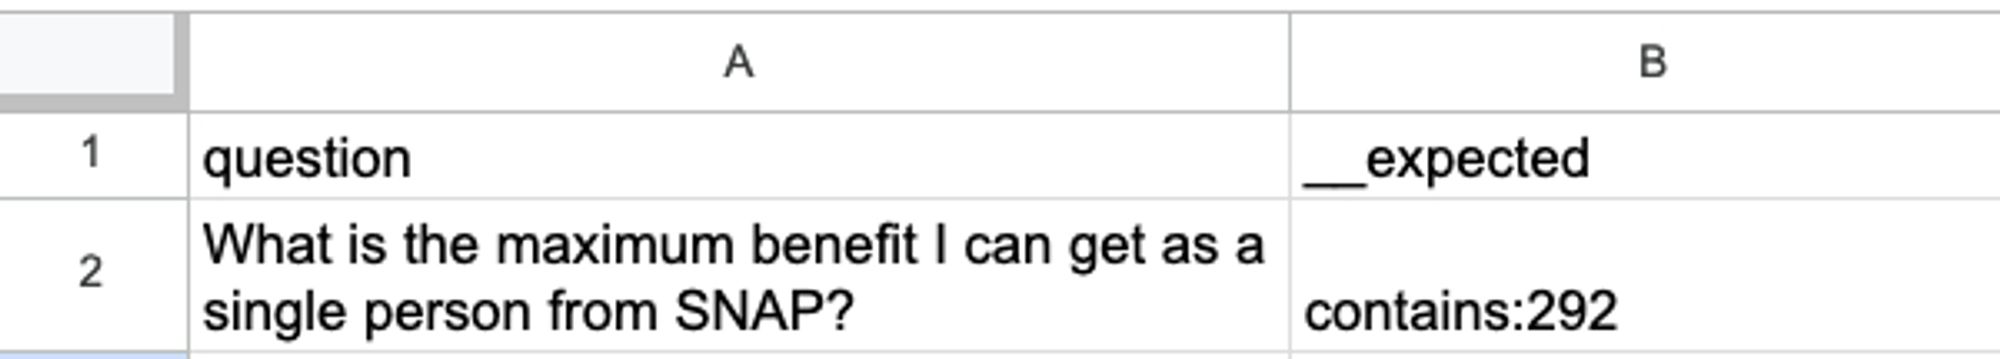 ”article, stated
Models used: GPT-4o-mini · Claude 3.5 Sonnet · Gemini 2.0 Flash Experimental · LLM-as-judge
Scale
- Propel tested three model families in the described factual test.“* We asked each of 3 different AI models (OpenAI’s GPT-4o-mini, Anthropic’s Claude 3.5 Sonnet, and Google’s Gemini 2.0 Flash Experimental)... * The same question: What is the maximum benefit I can get as a single person from SNAP?”article, stated
- Claude succeeded in about 73% of the non-representative factual cases.“In this specific (non-representative!) test set, we see Claude succeeding about 73% of the cases, while the other two models pass only about 45% of the cases.”article, stated
- The other two tested models passed only about 45% of cases.“In this specific (non-representative!) test set, we see Claude succeeding about 73% of the cases, while the other two models pass only about 45% of the cases.”article, stated
- One factual criterion expected the answer to include $292.“* Input prompt: “What is the maximum benefit I can get as a single person from SNAP?” * Criteria to evaluate the answer: it should include “$292””article, stated
Alternatives considered (roads not taken)
Use one generic eval for both public benchmark and internal product.
Rejected because: Benchmarking and product-assistant goals diverge after a common foundation.
Depend only on base-model knowledge.
Rejected because: Models gave outdated income-limit information, so external knowledge may be needed.
Only write hand-reviewed nuanced evals.
Rejected because: Factual tests are easier to automate and should be the next step.
Patterns
eval-driven-development (public-benefits AI)
Propel builds factual and nuanced SNAP evals before deploying a SNAP assistant.
llm-as-judge (evaluation)
Model judges are used for criteria such as reading-level accessibility.
rag-retrieval (knowledge freshness)
RAG is identified as relevant when models need current income-limit inputs.
human-in-the-loop-gate (domain expertise)
SNAP experts probe models and define concrete good/bad outputs.
Tradeoffs
Eval split
Chose Two evals with a common foundation over One universal SNAP eval.
Rationale: Public benchmarking and product guidance have different values and criteria.
Initial automation
Chose Factual tests first over Only nuanced model-judge tests.
Rationale: Objective facts are easier to write and automate.
Authoring interface
Chose Google Sheets through Promptfoo over Engineer-only code-based eval authoring.
Rationale: Domain experts need to contribute directly.
Gotchas (what bit them)
Base models can know outdated benefit facts.
Root cause: SNAP policy values change over time and model knowledge may lag.
Resolution: Test factual prerequisites and inject current knowledge with RAG or large-context inputs.
A benchmark objective may conflict with product-specific helpfulness.
Root cause: A client-facing assistant may penalize refusals differently from a general benchmark.
Resolution: Maintain separate eval goals on a common foundation.
Domain eval creation bottlenecks if only engineers can author tests.
Root cause: SNAP experts hold the knowledge but may not be software engineers.
Resolution: Use Promptfoo with Google Sheets to make eval creation accessible.
Evaluation
The project is an evaluation framework: expert model probing, factual test authoring, Promptfoo automation, multi-model factual comparisons, and LLM-as-judge checks for reading-level and nuanced criteria.
Metrics: Factual pass rate · Correct SNAP benefit amount · Reading-level accessibility · Model comparison · Outdated-information detection
Outcomes
- Claude passed about 73% of a non-representative factual test set.
- The other two models passed about 45% of cases.
- The eval identified outdated income-limit information as a problem that RAG or large context could address.
The source reports three tested models, a $292 factual answer criterion, about 73% Claude pass rate, and about 45% pass rate for the other two models.